LLM Cost Calculator
& Token Counter
Estimate your AI project costs across the top LLM models — then discover how DataGrout can cut those costs by up to 99.98%.
Interactive LLM Cost Calculator
Estimate token usage and costs across the top AI models
Configuration
In: $2/M · Out: $12/M · 1M context · Balanced — general purpose & coding
Estimated Costs
Token Breakdown
Cost per Query
Cost Split
Token estimates use ~4 chars/token approximation. Prices sourced from official provider pricing pages as of September 2026. Verify current rates before budgeting.
LLM Pricing Comparison
Input & output token costs per 1M tokens across leading models — September 2026
| PROVIDER | MODEL | INPUT / 1M TOKENS | OUTPUT / 1M TOKENS | PROMO / STANDARD | CONTEXT | NOTES |
|---|---|---|---|---|---|---|
| Mistral | Mistral Small 3.2 | $0.15 | $0.60 | 256K | Hybrid instruct + reasoning + coding (24B) | |
| DeepSeek | DeepSeek V4 Flash | $0.15 | $0.66 | $0.30 / $1.32 Peak hours | 1M | Fast, 1M context, thinking + non-thinking modes |
| OpenAI | GPT-5.6 Luna | $0.20 | $1.20 | 1M | Efficient — high-volume tasks | |
| OpenAI | GPT-5.4 nano | $0.20 | $1.25 | 400K | Lowest-cost — high-volume automation | |
| xAI | Grok 4.1 Fast | $0.20 | $0.50 | 2M | Volume tier — 2M context, lowest cost | |
| Gemini 3.5 Flash-Lite | $0.30 | $2.50 | 1M | Budget Flash — balanced cost & capability | ||
| Gemini 3.6 Flash | $0.375 | $1.875 | $0.75 / $3.75 Standard (from Jan 1, 2027) | 1M | Lowest-cost 3.x Flash | |
| Mistral | Mistral Large 3 | $0.50 | $1.50 | 256K | General-purpose, open-weight MoE (675B total) | |
| DeepSeek | DeepSeek V4 Pro | $0.66 | $1.98 | $1.32 / $3.96 Peak hours | 1M | Max capability, 384K output, 1M context |
| OpenAI | GPT-5.4 mini | $0.75 | $4.50 | 400K | Strong mini — coding, computer use, subagents | |
| Gemini 3.8 Flash | $0.75 | $3.75 | $1.50 / $7.50 Standard (from Jan 1, 2027) | 1M | Newest Flash — frontier speed & multimodal | |
| Gemini 3.7 Flash | $0.75 | $3.75 | $1.50 / $7.50 Standard (from Jan 1, 2027) | 1M | Prior Flash release — speed & multimodal | |
| Anthropic | Claude Haiku 4.5 | $1.00 | $5.00 | 200K | Fastest Claude, near-frontier intelligence | |
| xAI | Grok 4.3 | $1.25 | $2.50 | 1M | Cost-efficient reasoning, 1M context | |
| Gemini 3.5 Flash | $1.50 | $9.00 | 1M | Frontier intelligence + speed | ||
| Mistral | Mistral Medium 3.5 | $1.50 | $7.50 | 128K | Flagship — agentic & coding (128B params) | |
| OpenAI | GPT-5.6 Terra | $2.00 | $12.00 | 1M | Balanced — general purpose & coding | |
| Anthropic | Claude Sonnet 5 | $2.00 | $10.00 | 1M | Best speed/intelligence balance | |
| xAI | Grok 4.6 | $2.00 | $6.00 | 500K | Flagship — long-running agents, coding, research | |
| xAI | Grok 4.5 | $2.00 | $6.00 | 500K | Previous flagship — agentic tool calling | |
| OpenAI | GPT-5.4 | $2.50 | $15.00 | 1M | Affordable coding & professional work | |
| OpenAI | GPT-5.6 Sol | $4.00 | $20.00 | $5.00 / $30.00 Standard (from Nov 21, 2026) | 1M | Frontier coding & reasoning |
| Anthropic | Claude Opus 5 | $5.00 | $25.00 | 1M | Flagship — complex reasoning & agentic coding | |
| OpenAI | GPT-6 Astra | $10.00 | $50.00 | 1M | New flagship — long-horizon agentic work | |
| Anthropic | Claude Fable 5.1 | $10.00 | $50.00 | 1M | Highest tier — most demanding agentic work |
Green = low cost tier. Red = premium tier. Always verify pricing on official provider documentation before production budgeting.
Now see those costs live, as they happen
The calculator shows you what you could spend. Lumen shows you what you are spending — in real time. It intercepts your LLM API traffic and surfaces cost, token rate, and cache savings as live arc gauges. Think Activity Monitor for your AI bill.
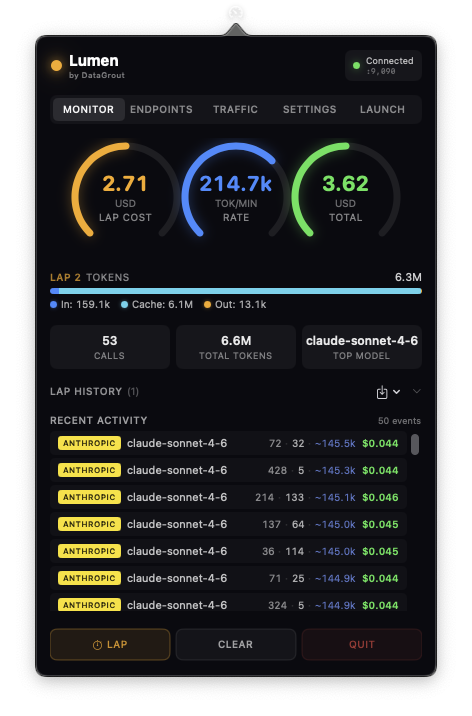
- Live arc gauges — cost and token rate updated on every API call
- Per-call cost breakdown with model attribution
- Cache hit visualization — see what you saved vs. what hit the LLM
- Multi-provider: OpenAI, Anthropic, Cursor, Google AI
macOS 14+ (native) · Linux & Windows (browser dashboard) · Privacy-first — content never stored
The complete loop
Estimate
This Calculator
Model token costs before you build or deploy.
Observe
Lumen
See live token rates and costs per call as they happen.
Optimize
DataGrout Platform
Cache, route, and compress to cut spend automatically.
Frequently Asked Questions
Ready to Cut Those Costs for Real?
The calculator shows the potential. DataGrout delivers it — through semantic caching, inference routing, and context optimization that work automatically.
Start free. No credit card required.